Counting Dependencies: Aggregation Rules and What Official Dependency Indices Identify
Stefane Fermigier (Abilian) · sf@abilian.com
Draft working paper v0.1, 2026-07-18. The paper proves three propositions, each with a proof and a numeric cross-check by brute force, plus a Monte-Carlo report on rank stability. The application reconstructs a published index from the published cells; no new measurement is made.
Abstract
European economic-security policy now rests on official dependency indices. The instrument in current use scores technology areas against a fixed list of dependency dimensions on a binary ordinal scale, counts the dimensions rated high, and reports the difference between that count and the corresponding count of reverse dependencies. We ask what such an index identifies.
Threshold counting and weakest-link exposure are different functionals and rank the same latent profiles differently, so an index that counts cannot represent a system its own authors describe as failing when one essential component fails. On a binary scale the weakest-link reading collapses outright. Where every unit scores high on some shared dimension, the maximum is constant across units and all ranking content comes from the additive rule. The choice of rule is then doing the work the data are assumed to do. Netting counts of high dependencies against counts of high reverse dependencies is a third distinct object, and because a binary scale discards intensity, the net count can invert the ordering of bargaining positions it is read as describing.
We reconstruct the index published for the European Commission from the cells it publishes. The reconstruction reproduces twelve of thirteen printed totals; the thirteenth row has seven high cells and prints six. The published prose groups five areas as showing "a net dependency of more than three types"; their net values run from minus one to three. Read as a slip for "at most three", the grouping holds with two exceptions: data analytics scores minus one, a net reverse dependency placed in a list of net dependencies, and microelectronics, at three, belongs to the group and is placed outside it. Every one of the thirteen areas scores high on digital infrastructures and software, so the weakest-link reading is degenerate on this data. Under random positive reweighting of the eight dimensions, applied to both tables, artificial intelligence remains the most dependent area on every draw, because its net row weakly dominates every other. The order below it is less stable: the areas with high reverse dependencies move most. We then state what a path-aware instrument has to supply instead, and connect the requirements to the measured-graph approach developed in the companion papers.
Keywords: composite indicators, economic security, strategic dependency, aggregation, interdependence, measurement.
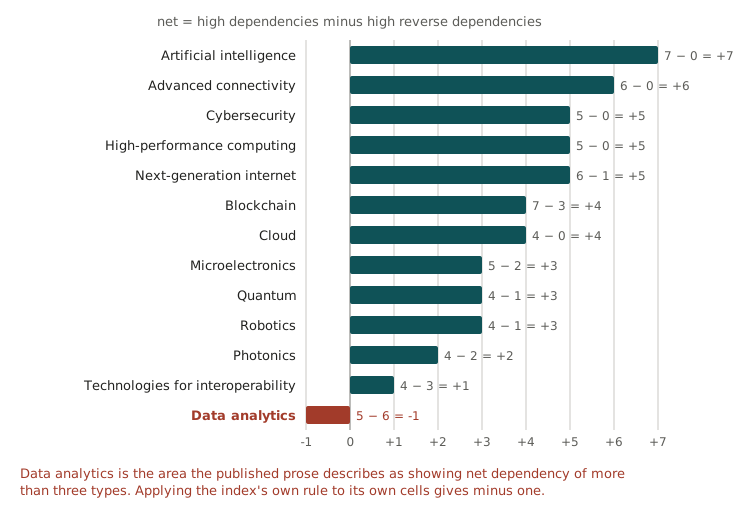
The published dependency index, reconstructed from its own cells: net count of high dependencies for thirteen technology areas. One area's score under the index's own rule contradicts the prose that describes it.
About this paper
| Programme | Path sovereignty |
| Genre | Draft working paper |
| Version | v0.1 |
| Date | 2026-07-18 |
| Full text | |
| Plain-language explainer | The index that counts |
Cite this paper
Fermigier, S. (2026). Counting Dependencies: Aggregation Rules and What Official Dependency Indices Identify.
Draft working paper v0.1, Abilian Econ Lab.
https://econ.lab.abilian.com/papers/counting-dependencies/